Senior SEO & AI Consultant | Adjunct Lecturer
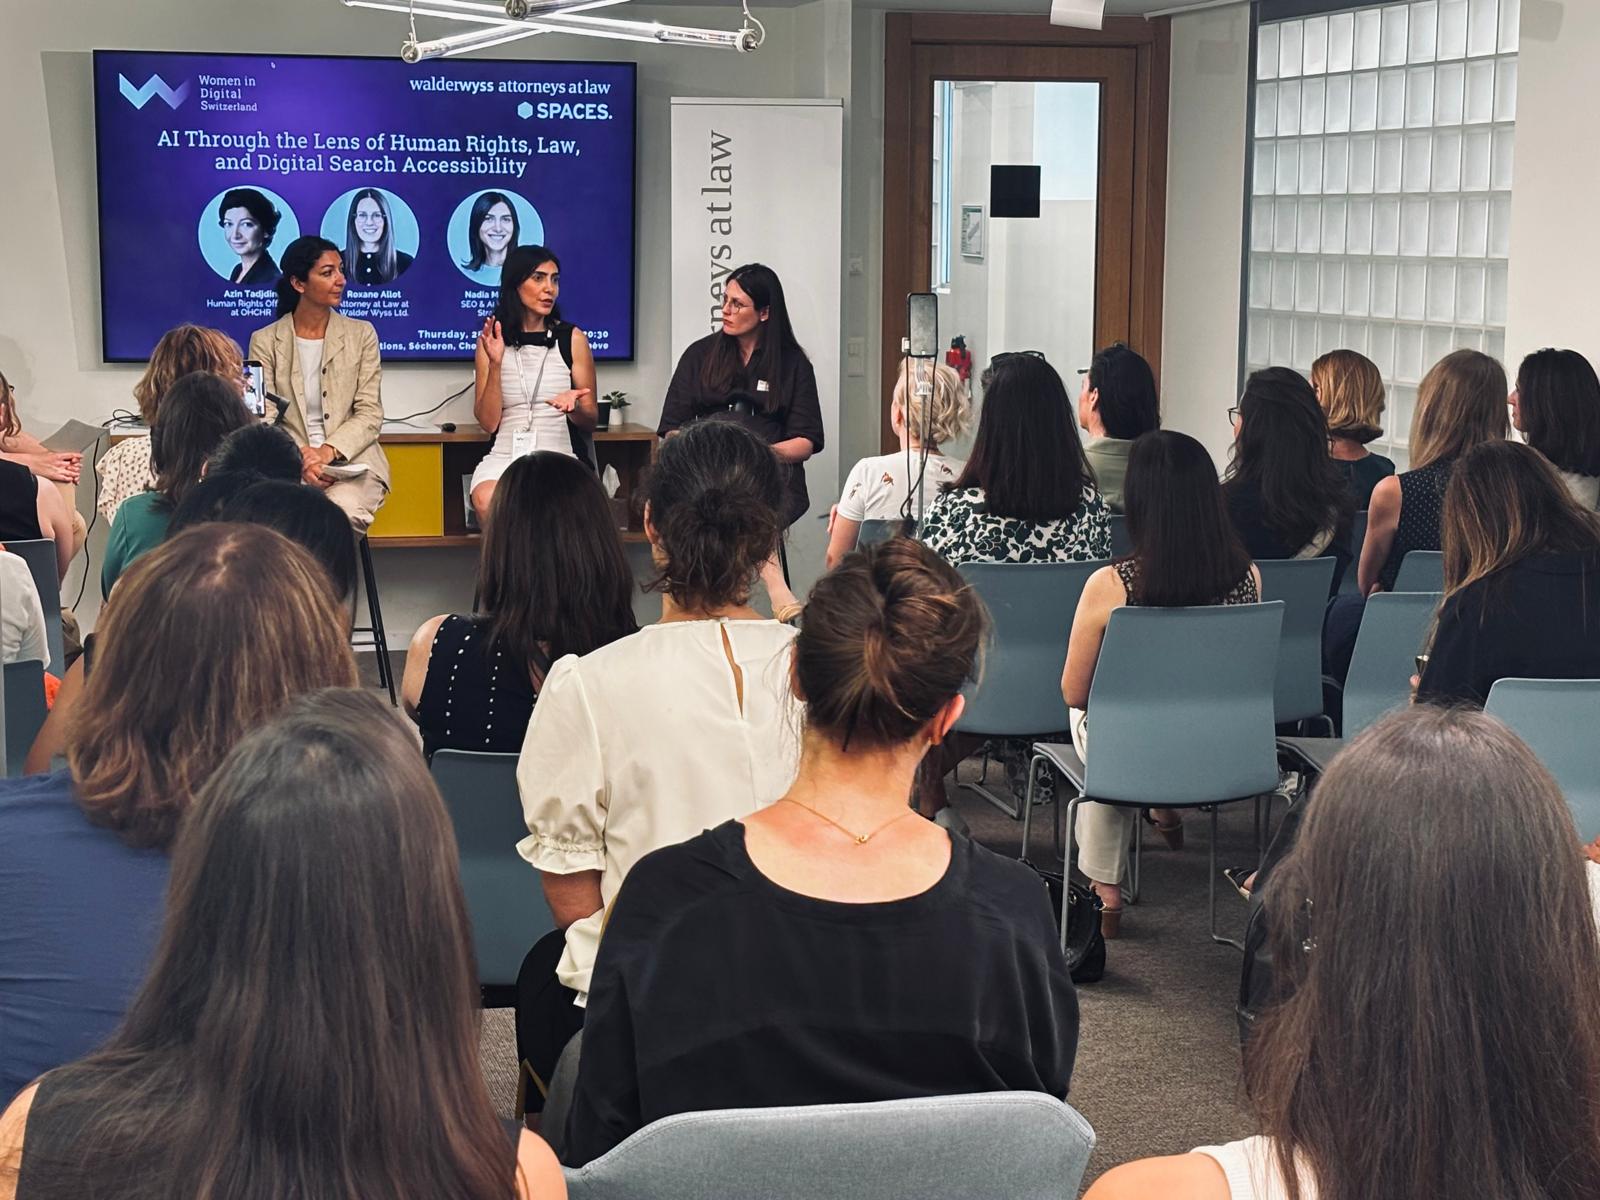
As part of a recent Women in Digital Switzerland event, hosted at Spaces Nations in Geneva, Nadia Mojahed, Founder of SEO Transformer and SEO & AI Visibility Strategist, joined a panel of experts to explore how artificial intelligence is reshaping human rights, regulation, and digital discoverability.
Alongside Azin Tadjdini, Human Rights Officer at the Office of the United Nations High Commissioner for Human Rights (OHCHR), and Roxane Allot, Attorney at Walder Wyss, Nadia shared insights on how AI-driven search is changing the way information is surfaced online, and what organisations can do to ensure their content remains visible, accessible, and representative in an increasingly AI-mediated digital landscape.
One of the key themes that emerged from the discussion was that discoverability is no longer just a tech or a digital marketing concern. As AI systems become the gateway to information, visibility increasingly influences whose voices are heard, trusted, and represented. Below is a summary of the key insights shared during the discussion.
The Discoverability Gap in the Age of AI
During the panel discussion, Nadia tackled one of the most critical challenges facing modern brands ‘the shifting mechanics of discoverability’.
For three decades, the fundamental architecture of the internet was engineered exclusively for human consumption. We designed interfaces, wrote copy, and mapped user flows to communicate with people, not artificial intelligence. This human-centric approach served the digital economy perfectly, right up until today.
That was not a problem, until now. AI agents are rapidly becoming the dominant layer through which humans access information online. They will not just answer questions; they will execute tasks, make recommendations, and take actions on our behalf. They are, in every meaningful sense, officially beginning to participate in our public life. And they are doing so by scraping, interpreting, and reconstructing the web as it currently exists — a web that was never designed for them.
This creates a profound and largely unacknowledged disconnect. The real world is full of verified voices, credible institutions, decades of business expertise, and hard-won human rights organizations. But AI does not see credentials. It does not recognize reputation the way humans do, they read code.
Verified voices, organizations with decades of credibility, legal expertise, or institutional trust, will not be as good as their code to AI. And most of the web, as it stands today, is a wall of ambiguous human text — bloated, poorly structured, and illegible to the machines that are increasingly deciding who gets found.
How Search Engines and AI Agents Read Your Website
They both visit your website. What they do when they get there could not be more different.
How Traditional Search Engines Work
Google Search operates in three distinct stages.
- First, crawling — automated programs called web crawlers, continuously explore the web to discover text, images, and video from pages. Think of crawlers as postal workers constantly walking every street on the internet, noting which buildings exist and what is written on their doors. While there is no single, mandatory central registry of all web pages, Google relies heavily on submitted XML sitemaps (Search engine navigation file) and follows links from known pages to discover new URLs.
- Second, indexing — once a page is crawled, the search engine like Google or Bing analyzes its content and stores the information in a large database. Think of this as the postal worker returning to the office and filing a detailed report about every building they visited — what it contains, what language it speaks, who it is for. During this stage Google also determines whether a page is the definitive version of its content or a duplicate of something that already exists elsewhere.
- Third, serving results — when a user searches, Google queries its index and returns the pages it determines are most relevant and highest quality, ranked programmatically based on hundreds of factors including location, language, and device.
- Critically, not every page makes it through all three stages. A page can be crawled but not indexed. It can be indexed but never served in results. Poor site architecture, low content quality, and technical errors can all stop a page from progressing — silently, without any notification to the site owner.
How AI Agents Read Your Website
AI Agents access your site through three primary lenses:
- Raw HTML: HTML is the underlying code that tells a browser what to display and how to organize it. Think of it as the architectural blueprint of a building — not what the building looks like painted and furnished, but the structural skeleton beneath. The agent reads this blueprint directly, analyzing how elements are nested, the logical hierarchy of the page, and the raw data that forms the site’s informational backbone. This allows the agent to understand relationships between elements — if a Buy Now button sits inside a product container, the agent infers that button belongs to that specific product.
- Screenshots: The agent takes a snapshot of the rendered page and uses a vision model to interpret it visually, the way a sighted person might glance at a page and immediately understand its layout. It can recognize that a search bar in the top right is a navigation tool, or that a large red Delete button carries more weight than a small Help link. Visual cues like color, size, and proximity all carry meaning. However, screenshot analysis is slow and resource-intensive, making it a fallback rather than a primary method when page structure is clear.
- The accessibility tree: This is a simplified, structured summary of a webpage generated automatically by the browser, originally designed to help screen readers assist visually impaired users. For an AI agent, it functions like a clean floor plan of a building that strips away all the decoration and shows only the doors, switches, and essential fixtures — every interactive element on the page described by what it does rather than what it looks like. It tells the agent: this is a navigation menu, this is a search field, this is a submit button.
A Single Signal Is Never Enough for AI Discoverability
Relying on any one of these inputs creates gaps. In the raw code alone, an agent might encounter an element with no clear label — something that has been visually styled to look and behave like a button, but carries no structural marker identifying it as one. A screenshot might show where that button sits on the page, but tells the agent nothing about what it triggers. The accessibility tree provides functional intent but lacks the layout context that helps the agent understand grouping and visual hierarchy.
Modern agents therefore combine all three. They use the code and accessibility tree to build a structured list of interactive elements, then cross-reference that with a visual rendering to understand layout and grouping. The result is a composite picture of your page — assembled from multiple signals simultaneously, the way a person might read a map, look at street signs, and glance at landmarks all at once to navigate a new city.
What This Means for Your Website
Generative AI does not work like traditional search. It digests vast amounts of data, breaks it down, and reconstructs an entirely new answer based on statistical patterns. When a source lacks the technical infrastructure to be recognized — no structured data, no entity signposting, no presence in a knowledge graph — AI engines do not cite it. They absorb it. The original idea gets reconstructed inside the AI’s response, but the author receives zero attribution, zero traffic, and zero visibility. The knowledge is extracted; the human voice is erased.
The practical implication is direct: Your website must send clean, consistent, unambiguous signals across all channels. A page that looks beautiful to a human but is built on unstructured code, lacks proper semantic roles, and loads key content in ways machines cannot process is, from an agent’s perspective, largely illegible. It is not that the agent dislikes your site. It is that the agent cannot read it.
Traditional search engines and AI agents both reward the same underlying quality: a site that is technically clean, semantically structured, and built with machine interpretation in mind. Without that, a search engine will simply not rank you higher. An AI agent will not find you, understand you, or trust you — and will move on to a source it can.
The Narrowness of the AI Visibility Window
Understanding how agents read your site is only half the picture. The other half is understanding how little room there is to be seen at all.
AI engines operate on a strict data diet. Think of it like a researcher who has one hour to write a briefing on a complex topic — they will go to the clearest, most organized sources first and ignore anything that takes too long to decipher. When generating an answer, AI systems pull from a limited range of content across the entire web, working within strict real-time processing limits per request and defaulting to the most structured, highest-ranking sources available. No clear information, ambiguous pages — they skip to the next source. If your content is not in that narrow slice, it does not receive a lower ranking. It receives no ranking at all.
Of the billions of pages that exist online, only a fraction are consistently retrievable and usable for AI citation. Many websites are bloated with unnecessary code, poorly organized, slow to load, or technically fragmented in ways that make machine extraction difficult. Many conversational AI systems depend heavily on traditional search indexes for live, real-time grounding. If a website fails to rank or get indexed conventionally, it is effectively cut off from the live data streams feeding these hybrid AI answer engines. The two layers of visibility are connected. Failing one means failing both.
This means that human rights data, verified legal information, or evidence-based research that is not structured cleanly for machine extraction does not get deprioritized. It gets cut off entirely. If a website lacks the technical signals that machines rely on — structured data markup, clear entity definition, logical information hierarchy, and consistent organization — it may never enter the narrow visibility window that AI systems use to formulate their answers. And a source that never enters that window does not exist — not to the machine, and therefore not to the person asking the question.
Who Bears the Cost of Technical Invisibility the Most
This is not a level playing field. Machine readability is increasingly shaped by resources, not relevance or real world context. Large platforms with significant technical capacity produce cleaner, more structured content because they can invest in meeting evolving technical standards.
As a result, organisations that lack these resources are often the very ones whose voices matter most, such as human rights defenders, legal aid organisations, grassroots movements without dedicated development teams, local businesses with limited technical expertise and competing priorities, and content creators or authentic voices operating outside the mainstream.
Most organizations are still focused on surface-level optimization — visual design, social media presence, basic SEO — while neglecting the structural foundations that determine whether machines can find, read, and trust them at all. Technical requirements are evolving rapidly, and many organizations either underestimate the issue or simply do not know what needs to be fixed.
This matters most at the moment of conversion. AI-driven discovery is increasingly tied to high-intent decisions — supporting an organization, making a purchase, donating, or choosing a service provider. Casual users may skim through generic searches, but decision-makers — and the AI agents acting on their behalf — use far more detailed, high-intent prompts that compare structured expertise, jurisdictions, certifications, case relevance, and verified institutional data. The higher the stakes of the decision, the more the AI relies on structured, verifiable signals to formulate its answer. An organization that is technically invisible at that moment does not just lose a ranking — it loses the conversion entirely, without ever knowing it was considered.
To be visible in those deeper, high-intent AI-driven queries, organizations need strong technical foundations, structured machine-readable data, and clear entity architecture that AI systems can confidently retrieve and validate. Verified voices become systematically excluded not because they lack credibility, but because they lack code legibility. If an AI agent cannot clearly identify and validate an organization through machine-readable signals, it will rely on alternative sources or probabilistic training data instead — and even when an institution does appear, it may have already lost control of its own narrative.
Ethical Considerations Surrounding AI
It is not an IT problem anymore — it is an ethics problem. AI engines do not just find information; they reconstruct it. What happens to original sources when they are not technically signposted? And why is machine-readability an ethics issue, not just a technical one?
The rise of AI tools brings with it a set of questions that are hard to answer. Who owns AI-generated content, particularly when it draws heavily from copyrighted material? How do we account for the human bias embedded in the data that large language models learn from? There are no simple answers, and legislation, industry standards, and professional norms are all still catching up. What matters now is that we build with these questions actively in mind rather than treating them as someone else’s problem to solve later. Three areas deserve particular attention.
- Content ownership and copyright: Copyright protects original works of authorship, and the rules vary significantly by country — many of which are actively debating how existing law applies to AI-generated content. Before publishing anything produced with AI assistance, you should be able to answer one question honestly: does this infringe on someone else’s copyrighted work? The answer is often harder to determine than it first appears, especially when AI output closely mirrors material it was trained on.
- Bias and discrimination: AI systems are built by humans and trained on data collected by humans, which means human bias and harmful stereotypes can be absorbed into the model and reproduced in its output. Any team building with or deploying AI tools should have a clear process for identifying and mitigating biased outputs before they reach users.
- Privacy and security: Sending data to third-party cloud APIs introduces exposure that may not exist in a purely in-house stack. When sensitive or personally identifiable information is involved, the stakes are higher still. Data transmission must be secure, access must be controlled, and systems must be continuously monitored — not configured once and assumed to be safe.
These concerns do not stop at content ownership and data handling. There is a deeper ethical dimension to how AI systems surface — or fail to surface — information at all. In a world where AI is rapidly becoming the primary lens through which people access knowledge, the ability to be correctly identified, attributed, and cited is no longer a minor technical detail. It is a question of epistemic equity, the fundamental right of who gets to be recognized as a source of knowledge in the first place.
The Consensus Problem and the Erasure of Minority Voices
To avoid generating false information, large language models look for consensus across the web — the most common, most repeated, highest-volume answer. This mechanism has a serious side effect. It systematically erases:
- Nuance — expert opinions that disagree with a popular but potentially incorrect majority
- Minority voices — cultural, regional, or marginalized perspectives that simply do not have the same volume of data online
- Innovation — new or disruptive ideas that have not yet become consensus
If you ask a crowd what the best food is, the answer can be pizza. It is a safe answer, but it renders an entire world of global cuisine invisible. The same dynamic plays out online: large platforms with significant content budgets dominate AI-generated responses not because their content is more accurate or more valuable, but because it is more machine-readable.
The Right to Be Found
Historically, censorship meant suppressing the right to speak. In the age of agentic AI, censorship increasingly means controlling the right to be found. We live in an era of infinite noise where anyone can publish — but autonomous AI agents act as the ultimate sorting layer for human attention. If you lack the technical infrastructure to pass through that filter, you are effectively muted by default, not by human decision but by algorithmic invisibility.
Legal and Regulatory Dimensions
Under emerging Swiss legislation and the EU AI Act, there is significant regulatory pressure for accountability and representative data to prevent algorithmic discrimination. Search engines are becoming legally liable for spreading misinformation. To protect themselves, these systems will increasingly filter out sources that cannot demonstrate high standards of data provenance — sources that cannot prove clearly where their information comes from. Non-compliance is not just an ethical risk; it is a visibility risk with legal underpinnings.
A further legal tension concerns the right to be forgotten. In traditional search engines, this right is established and enforceable — a person or organization can request that links to be removed from search results. AI does not offer the same recourse. Once information has been absorbed into a model’s training data, it cannot be selectively unlearned. There is no index entry to delete, no link to delist. The information becomes part of the model’s statistical understanding of the world, invisibly embedded in the answers it generates.
This creates a fundamental asymmetry: the right to be found may require significant technical effort to assert, while the right to be forgotten, once well protected, is significantly weakened in the generative AI context, with enforcement remaining largely unresolved in practice.
A Corporate and Humanitarian Obligation
Ensuring machine-readability is no longer purely an IT decision. It is a corporate and humanitarian obligation — a prerequisite for ensuring that truth, compliance, and human advocacy can actually be found, credited, and protected in the age of AI. The technical choices made about how content is structured and signposted are, in effect, choices about whose knowledge counts and whose voice gets heard.
What You Can Do: A Practical Framework for AI Visibility
Your website is no longer a digital brochure for human eyes. It is a structured information database meant to be ingested by machines. Before you think about creative marketing or UX design, your site must have absolute technical integrity. In an AI-driven landscape, if your data architecture is messy, AI search engines — Perplexity, ChatGPT, Google — will either ignore it or misinterpret it. Technical readiness is no longer a competitive advantage. It is the ticket to admission.
The starting point is a simple diagnostic framework: the three C’s of AI readiness.
- Can AI agents find you?
- Once they find you, can they understand you?
- Once they find you and understand you, can they trust you?
These three questions map directly onto four practical pillars — two technical, two content-related — that determine whether your organization exists in the AI-driven web.
Pillar 1: Technical Readiness
The foundation is how your website is built and served to machines. Think of this as the difference between a well-organized filing cabinet and a pile of loose papers on a desk — the information may be the same, but only one of them can be searched efficiently.
In practice this means:
- Load critical information upfront. AI systems work within strict processing limits. If your most important content — who you are, what you do, where you operate — is buried in code that only loads after a user interacts with the page, machines will not wait for it. They will move on. Your key information must be present in the initial structure of the page, visible to machines before any interaction takes place.
- Use clean, descriptive page labels. Meta tags — the short descriptive labels attached to every page that humans rarely see but machines always read — should accurately and specifically describe the content of each page. Think of them as the label on a filing folder: vague or missing labels mean the folder gets skipped.
- Build with semantic HTML. HTML is the code that structures your page. Semantic HTML means using the correct structural building blocks for each type of content — proper button elements for buttons, proper link elements for links, proper heading levels for headings — rather than forcing generic containers to perform functions they were not built for. Machines are trained to recognize standard building blocks. Non-standard ones create ambiguity. When an agent encounters a visual element that looks like a button but is not coded as one, it may not recognize it as interactive at all. If standard HTML cannot be used, the element should at minimum be given an explicit role label telling machines what it is meant to do.
- Maintain a stable, consistent layout. AI agents that analyze your pages visually will be confused if the same element — a key button, a navigation menu, a form field — appears in a different location on different pages. Consistency is not just a design principle; it is a machine-readability principle. An agent that cannot reliably locate an element across pages will lose confidence in the site entirely.
- Eliminate hidden or invisible elements. Transparent overlays, hidden menus, and elements concealed behind other content create what are effectively invisible walls for machine analysis. If an interactive element is visually obscured, agents conducting visual analysis may discard it entirely — even if it is technically present in the code. Every element that matters to the user journey should be clearly visible and accessible.
- Make interactive elements large enough to be recognized. Visual analysis by AI agents filters out elements that are too small to be meaningfully interpreted. Any interactive element — a button, a link, a form field — that is required to complete an action should have a visible area large enough to register in visual analysis. Elements smaller than a few pixels in either dimension risk being filtered out entirely.
- Govern who gets access to your data. Not every crawler on the web should have unrestricted access to your site. By configuring your robots.txt file — a simple set of instructions that tells crawlers what they are and are not permitted to access — you can selectively block specific AI scrapers from absorbing your proprietary content into their training data, while keeping your public-facing brand information open for discovery. This is not about hiding from AI; it is about controlling which AI systems benefit from your data and how. For industry-specific organizations, technical readiness also means ensuring accessibility to the specialized bots that feed into larger models — not just the major general-purpose crawlers.
- Define a clear roadmap for AI context. While governing who gets access to your data controls where AI agents cannot go, ensuring they accurately synthesize your information requires a proactive map. This is where the emerging
llms.txtstandardbecomes a key technical pillar for organizations and non-profits.Anllms.txtfile is a clean, markdown-based file placed at the root directory of your website. It provides a concise, high-density index of your site’s most critical information, specifically formatted for processing by LLMs and autonomous browser agents.
Pillar 2: Semantic Translation and Entity-Based SEO
AI models do not understand the world through keywords the way traditional search engines did. They map relationships between entities — the distinct, identifiable things that exist in the world: people, organizations, places, concepts, events. The question an AI system is always trying to answer is not “does this page contain these words” but “do I know what this organization is, what it does, who it serves, and how it connects to other things I already know?”
This is where schema markup becomes your powerful tool. Think of schema markup as a translation layer between your human-facing content and the machines reading it. It is a standardized vocabulary of code that you add to your website to explicitly state facts about your organization in a language machines are built to read. Rather than leaving an AI system to infer that you are a legal aid organization based in Geneva, schema markup states it directly and unambiguously, along with your areas of expertise, your organizational relationships, and your key attributes.
Advanced schema markup transforms unstructured website text into an organized machine feed. It acts as a bridge between your site and the global AI knowledge graphs — the vast interconnected databases that search systems use to validate facts about the world. When an AI system looks up your domain or industry, schema markup is what ensures it sees your organization as a clearly defined, well-connected, authoritative source it can confidently cite.
Pillar 3: Information Gain
You cannot out-produce large platforms in sheer content volume. You can win on uniqueness and density.
AI engines actively look for content that introduces facts or perspectives not already present in their training data — a concept known as information gain. Think of it this way: if an AI system has already absorbed thousands of articles making the same general point, another article making that same point adds nothing. It will be ignored. What will not be ignored is content that exists nowhere else — raw data from your own field work, proprietary case studies, findings that contradict the mainstream consensus, and highly specific expert perspectives grounded in direct experience.
For smaller organizations and non-profits, this is actually a structural advantage. Your field reports, your lived experience, your primary research, and your direct documentation of events are precisely the kind of source material AI systems will pull from when looking for something to cite that generic content cannot provide. The organizations that assume they cannot compete with large platforms on content are often sitting on the most valuable content of all — they simply have not structured and published it in a way machines can find and extract.
Pillar 4: Trust Signals and Proof of Humanity
As AI-generated content floods the web, both human users and AI systems are becoming better at detecting it — and more skeptical of it. Users are developing what might be called AI fatigue: a growing preference for content that carries the unmistakable texture of genuine human experience. AI search engines are adapting accordingly, actively looking for signals that content comes from a real person with real knowledge and real experience.
Google’s E-E-A-T framework — which stands for Experience, Expertise, Authoritativeness, and Trustworthiness — is the most explicit codification of this shift. It is an attempt to surface content that machines cannot authentically replicate, because AI cannot have a physical experience, conduct a genuine primary interview, build a real community, or hold a professional credential earned through years of practice.
Smaller organizations and non-profits should lean into exactly this. Feature your individual experts and leaders prominently and by name. Publish video content and audio that carries the texture of real conversation. Share behind-the-scenes documentation of your work. Write with opinion, subjectivity, and specificity grounded in direct experience. Commission original photography. Build community forums where real people exchange real perspectives. These are the formats that stand out precisely because they are the hardest for AI to convincingly replicate — and therefore the formats that both human readers and AI systems are increasingly trained to trust.
By establishing technical integrity first and reinforcing it with unique content and genuine human trust signals, you ensure that your real-world excellence is fully visible, correctly attributed, and impossible for machines to overlook. The organizations that act on this now will not just survive the shift to AI-driven search. They will define who gets heard in it.
Definitions and FAQs
What is an entity?
In the context of AI and semantic search, an entity is any distinct, identifiable thing that exists in the world and can be unambiguously defined — a person, an organization, a place, a product, a concept, or an event. What makes something an entity is not just that it has a name, but that it has a stable set of attributes and relationships that machines can map and verify. Your organization is an entity. Your CEO is an entity. The jurisdiction you operate in is an entity.
A simple example illustrates why this matters: the word “Apple” means nothing to a machine without entity disambiguation. Is it the fruit? The technology company? The record label founded by the Beatles? Humans resolve this instantly from context. Machines need explicit signals — attributes, relationships, and structured data — to determine which Apple is being referenced and to connect it to the correct set of facts. This is entity recognition: the ability to distinguish not just words, but the distinct real-world things those words refer to.
When AI systems try to understand your website, they are not reading it the way a human would — they are looking for entities they can recognize, connect to other known entities, and validate against knowledge graphs like Google’s Knowledge Graph or Wikidata. A website full of human-readable text but lacking clearly defined entities is, from a machine’s perspective, a collection of words without meaning. Without entity clarity, an AI system may misidentify who you are, conflate you with another organization, or simply be unable to place you in any meaningful context — and an entity it cannot confidently identify is an entity it will not cite.
What is schema markup and why is it important?
Schema markup is a standardized vocabulary of code—developed at Schema.org and supported by major search engines like Google and Microsoft—that you add to your website to explicitly state facts about your content, converting unstructured human language into an organized data feed that AI systems can instantly validate.
Where a human reading your homepage understands that you are a legal aid organization based in Geneva, a machine without schema markup has to guess. With schema markup, you state it directly in a language machines are built to read: what type of organization you are, where you operate, who leads it, what services you offer, and how all of those elements relate to each other. Think of it as a translation layer between your human-facing content and the machine intelligence trying to interpret it. Schema markup is what turns your website from an ambiguous document into a structured data source—one that AI systems can confidently extract from, cite, and connect to the broader knowledge graph of the web.
What is the difference between AI engines and traditional search engines?
The distinction comes down to two fundamental differences: how they store information, and how they retrieve it when you ask a question.
Traditional search engines like Google and Bing crawl the web continuously, map links between pages, and store everything in a massive database called an inverted index — think of it as an enormous, constantly updated library catalog. When you search, they query that catalog and return a ranked list of links. How quickly new content appears in results varies significantly depending on the authority of the site and how frequently Google’s crawlers visit it — new or smaller sites can take days or weeks to be indexed.
AI systems are more varied and should not be treated as a single category.
Pure language models (such as ChatGPT without browsing enabled) do not index or store pages at all. During a training phase, they read vast amounts of web content and compress what they learn into mathematical patterns called weights — effectively memorizing how concepts connect rather than saving the actual pages. Their knowledge has a cutoff date, and they cannot access anything published after training without additional tools.
AI search systems (such as Perplexity or Bing Copilot) work differently. They combine a language model with live web retrieval — searching the web in real time for each query, pulling relevant sources, and using them to generate a grounded, cited answer. These are increasingly the norm rather than the exception among consumer-facing AI search products.
| Feature | Traditional Search (Google, Bing) | Pure AI Models (ChatGPT without browsing) | AI Search Systems (Perplexity, Bing Copilot) |
|---|---|---|---|
| How they store data | Live inverted index of pages and URLs | Neural network weights encoding patterns from training data | Combine weights with live retrieval indexes |
| Real-time access | Crawls continuously; indexing speed varies significantly by site authority | No real-time access; limited by training cutoff | Retrieves from the live web in real time for each query |
| Search mechanism | Keyword and PageRank matching | Generates answers from learned patterns alone | Retrieves relevant sources then generates a grounded answer |
| Processing bottleneck | Speed of crawling, sorting, and retrieving billions of URLs | Compute cost of generating tokens in real time | Both retrieval latency and generation compute cost |
| Output | Ranked list of links to external pages | Conversational answer based on training data | Conversational answer with inline citations to live sources |
The practical implication for your organization is that visibility now requires satisfying multiple different systems simultaneously — a traditional search index, a training data corpus, and a live retrieval layer — each of which reads and evaluates your content differently.
How do AI systems know things about my brand?
There are three ways your brand can appear in an AI-generated answer.
- Training Data — the model’s “memory” During training, models ingest massive datasets of web pages, books, articles, and code. Information learned here becomes general knowledge embedded in the model. The catch is that this knowledge has a cutoff date, so anything that changed or launched after training may simply not exist in the model’s memory.
Implication: The model can recall concepts, brands, and relationships — but that knowledge can be outdated because training happens periodically. Example: If a brand appeared frequently on the web before the model’s training cutoff, the model likely “knows” it as a concept.
- Retrieval / RAG — the “open book” Modern AI search systems increasingly use Retrieval-Augmented Generation (RAG). Rather than relying on memory alone, the system searches a live index, retrieves relevant documents, and uses them as context to generate its answer — in that order. the system searches an index, which may be a live web index, a curated database, or a static document store, retrieves relevant documents, and uses them as context to generate its answer.
Implication: This is how AI systems stay current and verifiable. If your site cannot be crawled or indexed, it cannot be retrieved and cited. Example: When an AI answer includes sources or citations, those typically come from a retrieval step.
- Indirect Knowledge — the “echo effect” Even if your website isn’t directly retrieved or heavily represented in training data, an AI system can still mention you if other sources talk about you — including news articles, reviews, social discussions, third-party directories, and research papers. In this case, the model’s understanding of you is mediated entirely through those secondary sources.
Implication: Your brand’s accuracy in AI answers depends on what others have written about you, not what you say about yourself. Example: A restaurant might block AI crawlers, but if major review sites discuss it, the AI may still recommend it based on those sources.
Why this matters: if you want accurate, primary-source information about your brand driving AI answers, your content needs to be crawlable, indexable, and structured so AI systems can correctly interpret your entities and verify facts about you.
The Stakes Are No Longer Just Technical
Human rights, legal frameworks, and AI are more deeply interconnected than most organizations yet recognize. AI is being discussed from many angles — innovation, productivity, risk — but at its core it touches something more fundamental: our right to access information, our right to equal representation, and the legal frameworks designed to protect both.
As AI becomes agentic — meaning it no longer just answers questions but takes actions on behalf of humans — it is officially participating in public life. It books appointments, files requests, surfaces recommendations, and filters what exists. In a world where people rely on the internet above all else to find information, having diverse voices present and legible to these systems is not a preference. It is a democratic necessity.
And yet the barrier to that participation is now technical. You can write the most flawless, ethically sound human rights policy, or build a business that is fully legally compliant, but if your organization’s digital footprint is not semantically marked up, structured, and translated for machines, you do not exist to the AI. An AI agent cannot respect your rights, and it cannot evaluate your legal compliance, if it cannot crawl, read, or understand your data in the first place.
Technical integrity is the ultimate gatekeeper for your presence. The rules of machine-readability are not optional fine print — they are the new conditions of visibility. Do not leave your data narrative to a probabilistic machine. Fix your technical architecture. Because ensuring your website speaks to AI is not just a business decision. It is how we protect truth, law, and human advocacy in the age of intelligence.
Where to Go From Here
The room in Geneva was a beginning. The work continues from here.
The shift described in this article is not coming, it is already here. AI agents are already filtering who gets found, who gets cited, and whose version of events gets told. The organizations that act on this now will not just survive that shift. They will shape who gets heard within it.
As outlined in the practical framework, if you want to understand where your organization stands, return to the three diagnostic questions above. If you are unsure of the answers, that is the place to begin.
If you need support, feel free to get in touch.
SEO Transformer Highlights
- Featured as one of the top women in tech in Switzerland to follow in 2022!
- See my boring SEO predictions at I pullrank
- Sitechecker's study is finally out!! SEO Transformer Advice & other 90 women on gender diversity in SEO.
Community SEO Workshops in Switzerland and Beyond
Join our community SEO workshops online and learn about search developments, digital marketing and more.
SEO in the Age of AI: What You Need to Know
SEO Now Includes AEO, LLMO & GEO
- Provide direct answers (AEO)
- Be easily understood by large language models (LLMO)
- Be effective for generative search (GEO – Generative Engine Optimization)
- AI can accelerate content creation and research, but it cannot replace human expertise. True authority comes from your unique experience and insights.
- With the rise of AI-generated content, Google is prioritizing E-E-A-T (Experience, Expertise, Authoritativeness, and Trust).
- AI can streamline parts of the process, but building brand authority and trust still requires a consistent, long-term strategy- Among all digital channels, SEO remains one of the most sustainable investments, delivering the highest ROI over time.